
Trying out Twarc
I’ve had a bit of a play with Ed Summer’s Twarc tool before, but here I’m documenting my first attempt to do something a bit more systematic.
Over the last few years ‘#australiaday’ tweets have been ‘curated’ by the National Museum of Australia and Twitter and stored in a ‘time capsule’ (what does that even mean?). I thought it was important for someone to be documenting alternative views of Australia Day, so I decided to have a go at harvesting ‘#invasionday’ tweets using Twarc.
Setting up
Twarc is a Python tool and can be easily installed with pip install twarc. To configure it you need to obtain a set of four access tokens for the Twitter API. Once you have your keys the twarc configure command will ask you for your keys and save them to a .twarc file in your home directory.
The Twarc utilities aren’t installed when you run pip, so if you want to use things like the deduplicate script just clone a copy of the Twarc GitHub repository into your local directory.
Harvesting
Twarc provides two ways of harvesting tweets – search looks for matching tweets from the last week or so, while filter listens to the Twitter stream for anything new. I decided to combine the two approaches to try and get as much as possible. I’m not sure if there’s an optimal mix of search versus filter – I went a bit overboard and fired off almost daily searches. I knew this would result in lots of duplicates, but I thought it might increase my coverage. Perhaps this was just wishful thinking – I don’t really know enough about the coverage of the Twitter API.
To run a search you just do:
$ twarc search invasionday > invasionday-search.json
And to filter:
$ twarc filter invasionday > invasionday-filter.json
The filter command will sit around waiting, but I found that it sometimes stopped working. I suspect my internet connection might have dropped out.
Anyway after about a week I ended up with the following files:
-rw-r--r--     1 tim  staff      542490 23 Jan 17:35 invasionday-filter-20170122.json
-rw-r--r--     1 tim  staff      164501 24 Jan 17:46 invasionday-filter-20170123.json
-rw-r--r--     1 tim  staff    20143208 26 Jan 09:54 invasionday-filter-20170124.json
-rw-r--r--     1 tim  staff   188208128 28 Jan 10:20 invasionday-filter-20170126.json
-rw-r--r--     1 tim  staff     1768917  1 Apr 12:36 invasionday-filter-20170128.json
-rw-r--r--     1 tim  staff     9666495 22 Jan 12:50 invasionday-search-20170122.json
-rw-r--r--     1 tim  staff     8191817 23 Jan 17:38 invasionday-search-20170123.json
-rw-r--r--     1 tim  staff    11634605 24 Jan 17:46 invasionday-search-20170124.json
-rw-r--r--     1 tim  staff    15271533 25 Jan 18:39 invasionday-search-20170125.json
-rw-r--r--     1 tim  staff    29014598 26 Jan 09:55 invasionday-search-20170126-1.json
-rw-r--r--     1 tim  staff   107195725 26 Jan 18:33 invasionday-search-20170126-2.json
-rw-r--r--     1 tim  staff   160754085 27 Jan 09:14 invasionday-search-20170127.json
-rw-r--r--     1 tim  staff   176985132 28 Jan 10:36 invasionday-search-20170128.json
-rw-r--r--     1 tim  staff   175328710 29 Jan 14:48 invasionday-search-20170129.json
Combining json files
First step in processing was to combine all the .json files into one. Just do:
$ cat invasionday* > combined.json
This resulted in one 909mb JSON file containing 134,062 tweets.
I found that it’s worth checking that none of the files have been truncated before you combine them. Otherwise you’ll get errors later.
Deduplicate tweets
Twarc provides a useful utility function for removing duplicate tweets. Just do:
$ twarc/utils/deduplicate.py combined.json > deduped.json
This resulted in a 228mb JSON file containing 32,626 tweets. So yes, given that I had about 100,000 duplicates I think you could say I overdid the searching…
Sort
This wasn’t really necessary, but I thought I’d try it – sort tweets in id order (basically equivalent to sorting by the time tweeted):
$ twarc/utils/sort_by_id.py deduped.json > sorted.json
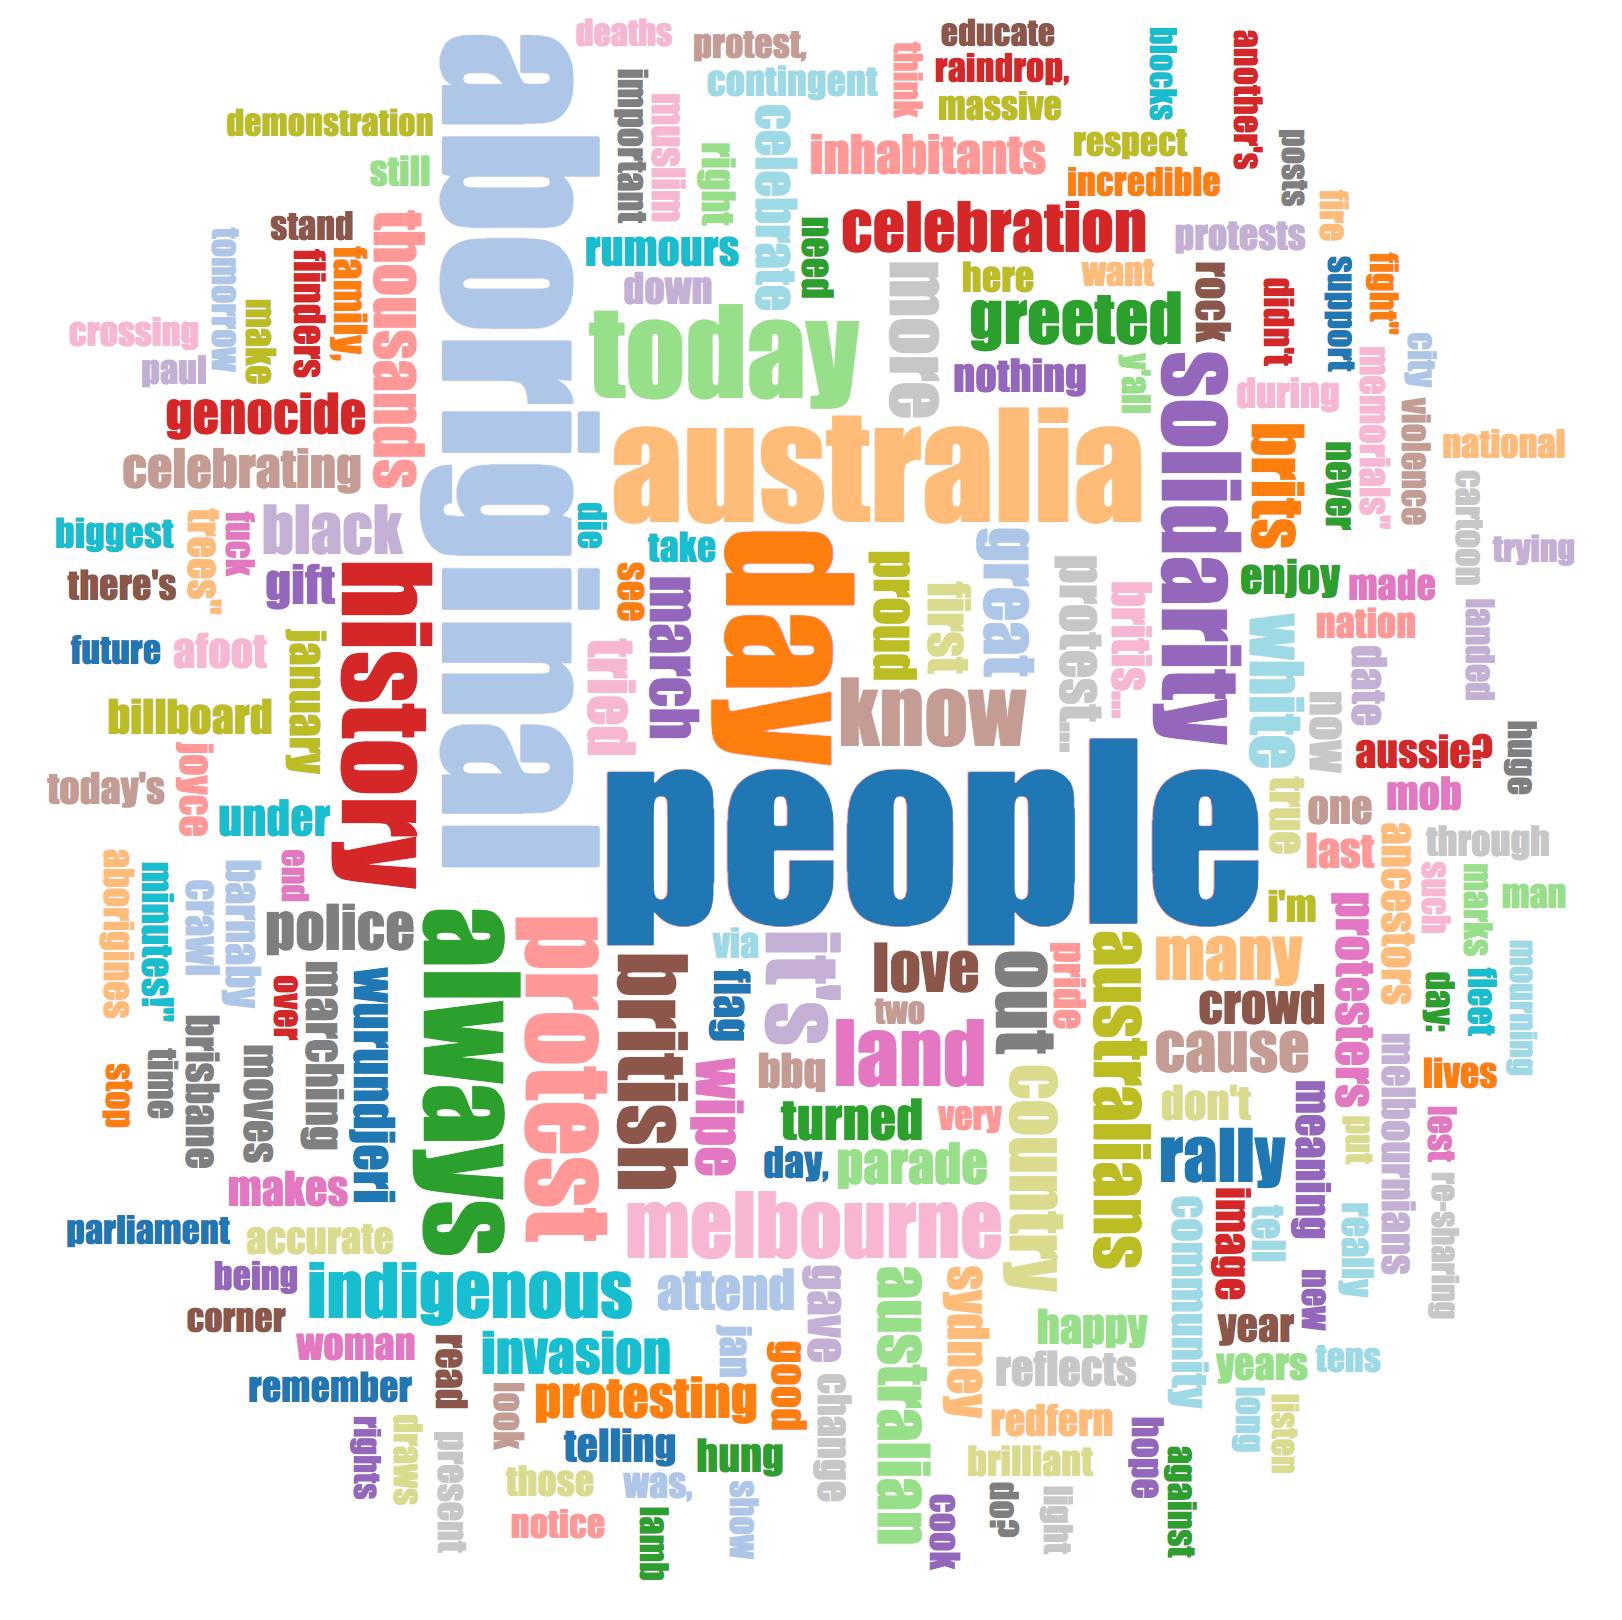
Make a word cloud!
$ twarc/utils/wordcloud.py deduped.json > wordcloud.html
Dehydrate
Twitter’s terms of service suggest that you shouldn’t share large amounts of harvested Tweets. To get around this, Twarc offers a dehydrate function that extracts just the Twitter ids. These can later be rehydrated using Twarc to retrieve the full details from Twitter.
$ twarc dehydrate sorted.json > invasionday-ids.txt
How many tweets do I have?
The JSON files created by Twarc have one tweet per line. So a quick way to find out how many tweets you have is to count the number of lines in the file.
$ wc -l < deduplicated.json
    32626
Remove retweets
How many original tweets were there? Remove retweets:
$ twarc/utils/noretweets.py unshortened.json > tweets_noretweets.json
Then:
$ wc -l < tweets_noretweets.json
    7058
Unshorten urls
Twitter returns some, but not all, unshortened urls. Twarc provides an unshorten script to help you get as many full urls as possible. These are then saved in the JSON file using the unshortened_url key.
To use the script you have to have unshrtn running – this is a node based web service that unshortens urls. I installed Docker, cloned the repository, and then followed the instructions on the GitHib site.
During the build phase I got an error message saying that the user with the uid 1000 already existed. I fixed this by just editing the Dockerfile to remove ` –uid 1000` from line 6.
The run command also resulted in an error – it seems the app was trying to bind to port 80, where I was already running a webserver. I just changed the command to docker run -p 3000:3000 -d -t unshrtn:dev and all seemed fine.
I could then do:
% sorted.json | twarc/utils/unshorten.py > unshortened.json
Get the urls
To save all unique urls to a file:
$ cat unshortened.json | twarc/utils/urls.py | sort | uniq > urls.txt
How many are there?
$ wc -l < urls.txt
    2754
To save all unique urls to a file, count them, and rank in order of popularity :
$ cat unshortened.json | twarc/utils/urls.py | sort | uniq -c | sort -nr > urls-ranked.txt
Neat trick huh? The -c flag on uniq adds a count which can then be used to resort.
Get images
To get list of unique image urls:
$ twarc/utils/image_urls.py unshortened.json | sort | uniq > images.txt
How many are there?
$ wc -l < images.txt
    1208
Once you have a file containing all the image urls, you can save them all with wget:
$ mkdir images
$ cd images
$ wget -i ../images.txt
Peek at a tweet
To show the first tweet in file nicely formatted way:
$head -1 deduped.json | jq '.'
If you don’t have JQ installed, you’ll need to brew install jq first.
Note that the Twarc JSON files save one tweet (JSON object) per line. I started off trying to treat them as arrays and got into trouble.
The results
My #invasionday collection summary: 32,626 tweets (7,058 original), sharing 2,754 unique urls, and 1,208 images. Harvested using Twarc. pic.twitter.com/jlasdg13Zk
— Tim Sherratt (@wragge) April 1, 2017
